The problem: a fresh start every session
Each new session starts blank. The agent does not remember the correction you gave yesterday, so you give it again. And again.
I wanted the agent to keep a mistake once it had been made, and avoid it next time without me repeating myself.
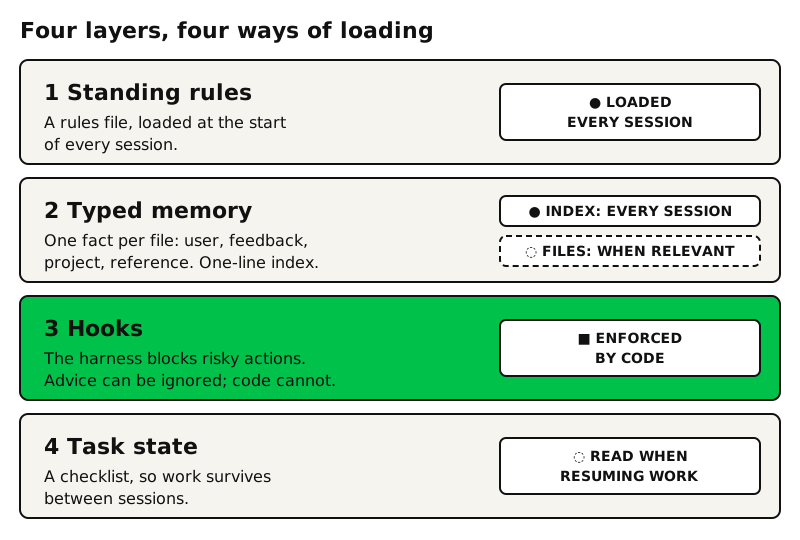
The setup: four layers
Nothing here is fancy. It is a handful of plain files and one small script.
- A standing rules file. Short, always loaded. It holds the basics and one key rule: check the memory index first.
- Typed memory files. One fact per file, each with a type: user, feedback, project or reference. A one-line-per-file index lists them all.
- Hooks. Small scripts that run on tool calls. They enforce the rules that must never be broken.
- A task checklist. A file with the steps and their status, so a long job survives a restart.
A worked example in three steps
Here is the whole loop in ten seconds. The three steps below go through it one frame at a time.
1. A mistake happens
The agent runs git push without checking the repo first, and the push is rejected because a teammate had changed the same file. I tell the agent what went wrong.
2. It becomes a memory
The agent saves a feedback file. The important parts are two lines: Why and How to apply. It also adds one line to the index.
---
name: check-git-status-first
description: Run git status before editing or pushing
type: feedback
---
Check the repo state before changing anything.

Why: A push once overwrote a
teammate's change.

How to apply: Run git status before
editing, and again before any push.
# memory/MEMORY.md
- [Check git status first](feedback_git_status.md)
Run it before editing or pushing
- [Project: reports tool](project_reports.md)
Where it runs, how it deploys3. Next session it does the right thing
A new session starts and the index loads. I ask for a small edit and a push. The index line "Run it before editing or pushing" matches the task, so the agent opens that one file and runs git status first.
Why not one big log?
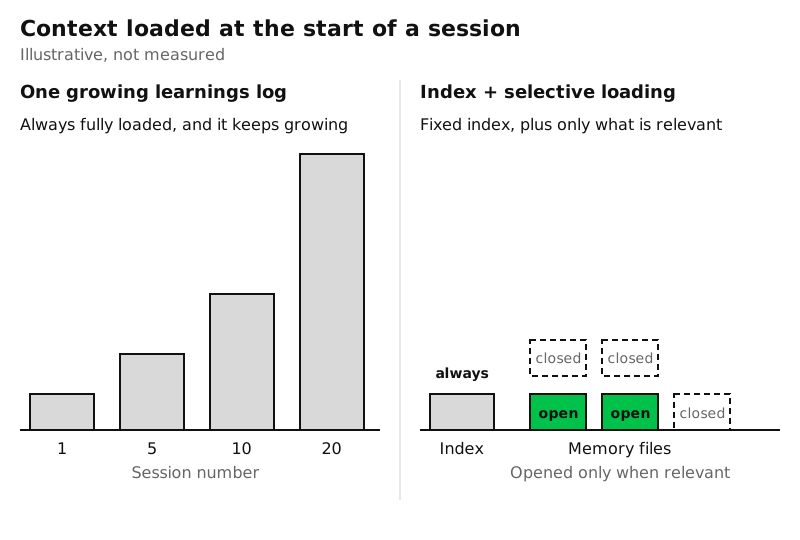
A single growing learnings log is the obvious first try. It works for a week or two. Then it gets in the way.
- Selective loading. The index is tiny. Only matching files are opened, so context stays small.
- The Why. With a reason attached, the agent can judge edge cases instead of following a rule blindly.
- Update in place. One topic lives in one file. You change it, so old and new advice never disagree.
- Hooks. Advice can be ignored. A hook cannot. Critical rules go there.
Honest limits
- It needs pruning now and then. Old memories go stale.
- A memory can be wrong. Treat it as a hint and check it against the real state.
- There is no automatic capture. Either you ask the agent to save a lesson, or it decides to. Some get missed.
How to implement
- Create a memory folder with an empty index file named MEMORY.md.
- Write three starter memories: one about you, one correction you give often, and one fact about a project.
- Add a line to your rules file: read the index first, and open only the files that match the task.
- Add one hook for your worst mistake, such as blocking a delete command until you approve it.
Start small. Three memories and one hook already change how the next session feels.